Hermetic update #3: from single questions to actual conversations with your data
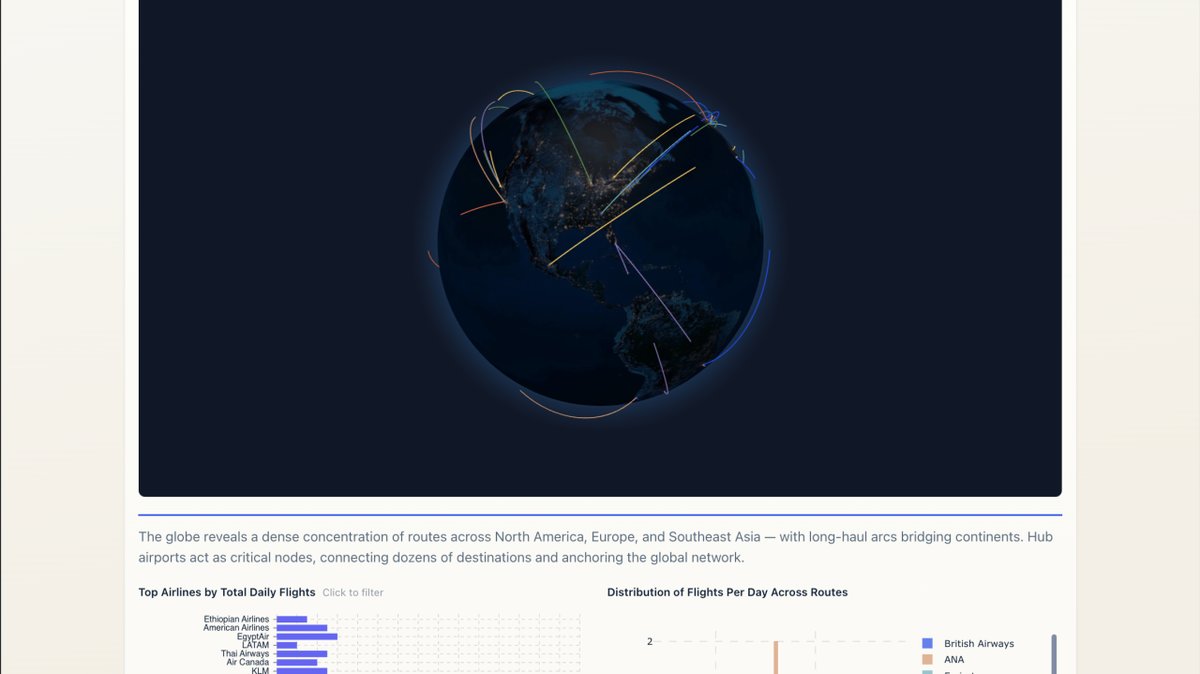
TL;DR: Hermetic now supports conversational follow-ups (the LLM remembers what you just asked), persistent history with re-run against fresh data, local Parquet/DuckDB file analysis, and a lot of reliability work across all 31 chart types. Still open source, still local-first. github.com/achalp/hermetic
The last update covered a lot of ground: warehouse connections, local LLM inference, smart suggestions, output styles, the UI redesign. That release made Hermetic usable. What shipped since then is about a specific gap I kept running into.
Hermetic could answer a question, but it couldn’t have a conversation. You’d ask something, see a chart, notice something odd in one of the segments, and then have to start over just to ask the obvious follow-up. That’s not how anyone actually explores data. You build on what you just saw.
That loop (ask, learn, follow up, come back later) is what the last few weeks focused on.
Follow-up questions that actually follow up
Hermetic now keeps conversation context on the server. When you ask a follow-up, the LLM gets the full history: what you asked, what code ran, what came back. So “exclude outliers and re-run” works. “Break that down by quarter” works. “Compare that to last year” works, without re-explaining the setup.
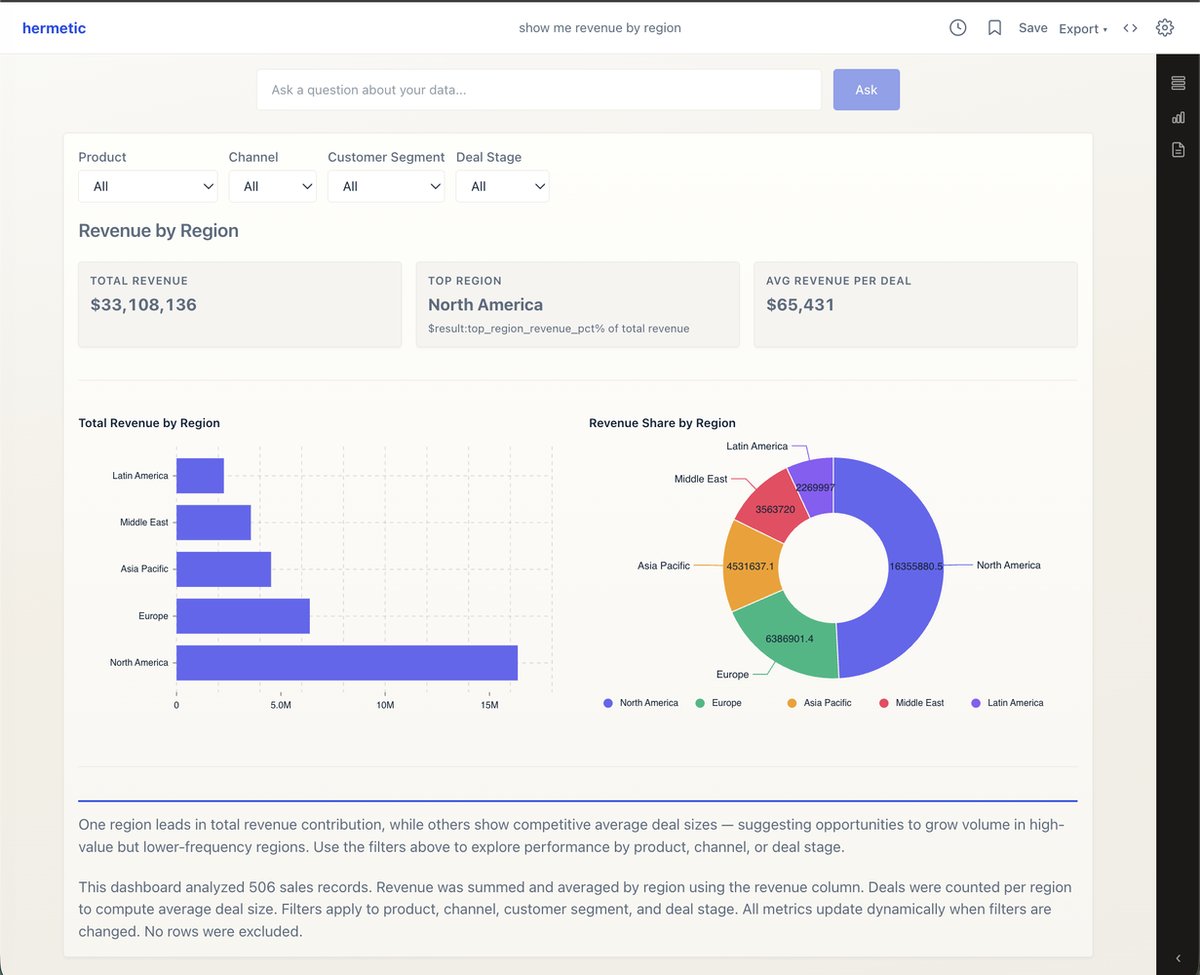
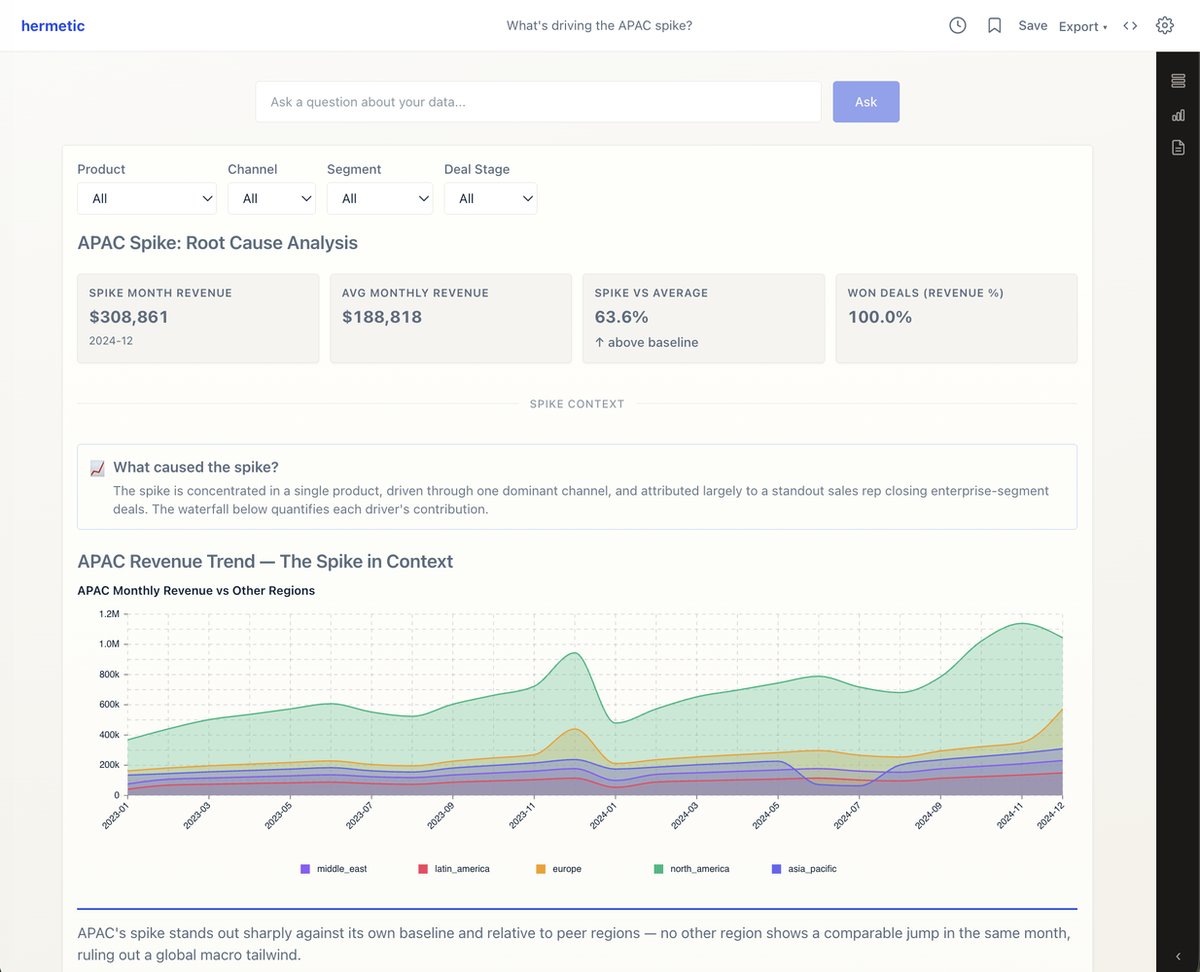
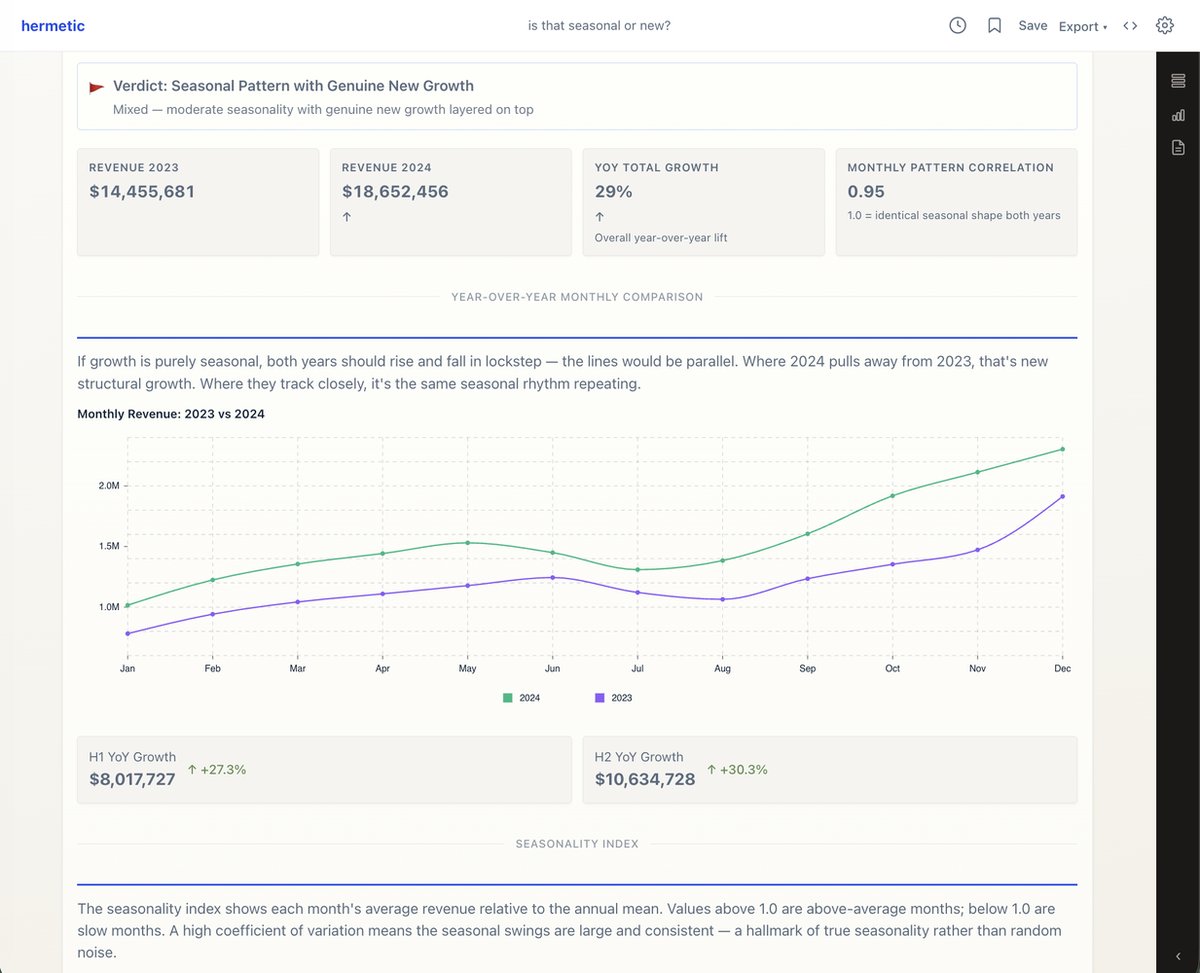
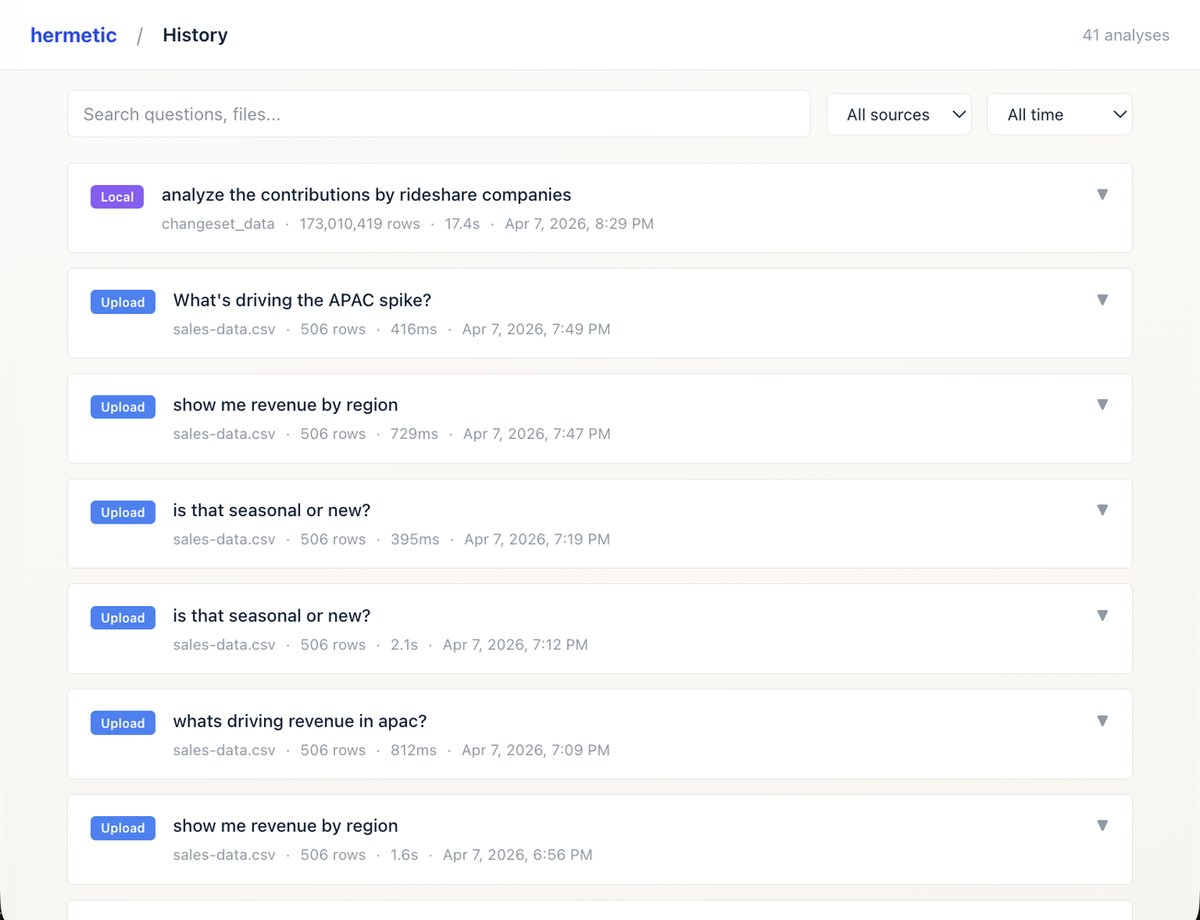
In practice this changes how you use the tool. Instead of trying to craft one perfect question, you just start somewhere and iterate. “Show me revenue by region.” OK, interesting, APAC is way up. “What’s driving the APAC spike?” Looks like it’s a few large deals. “Is that seasonal or new?” Each question builds on the last. The tool keeps up instead of making you repeat yourself.
History that sticks around
Before, history was in-session only. Close the tab and it was gone. Now every analysis auto-saves to disk: generated code, results, visualizations. History survives restarts. There’s a dedicated page to browse it, and you can restore any previous result instantly or re-run it against fresh data.
The re-run part matters. A dashboard you built last week re-executes against this week’s numbers. Bookmark the ones you care about. It turns history from a log into something you actually go back to.
Parquet and DuckDB, not just CSVs
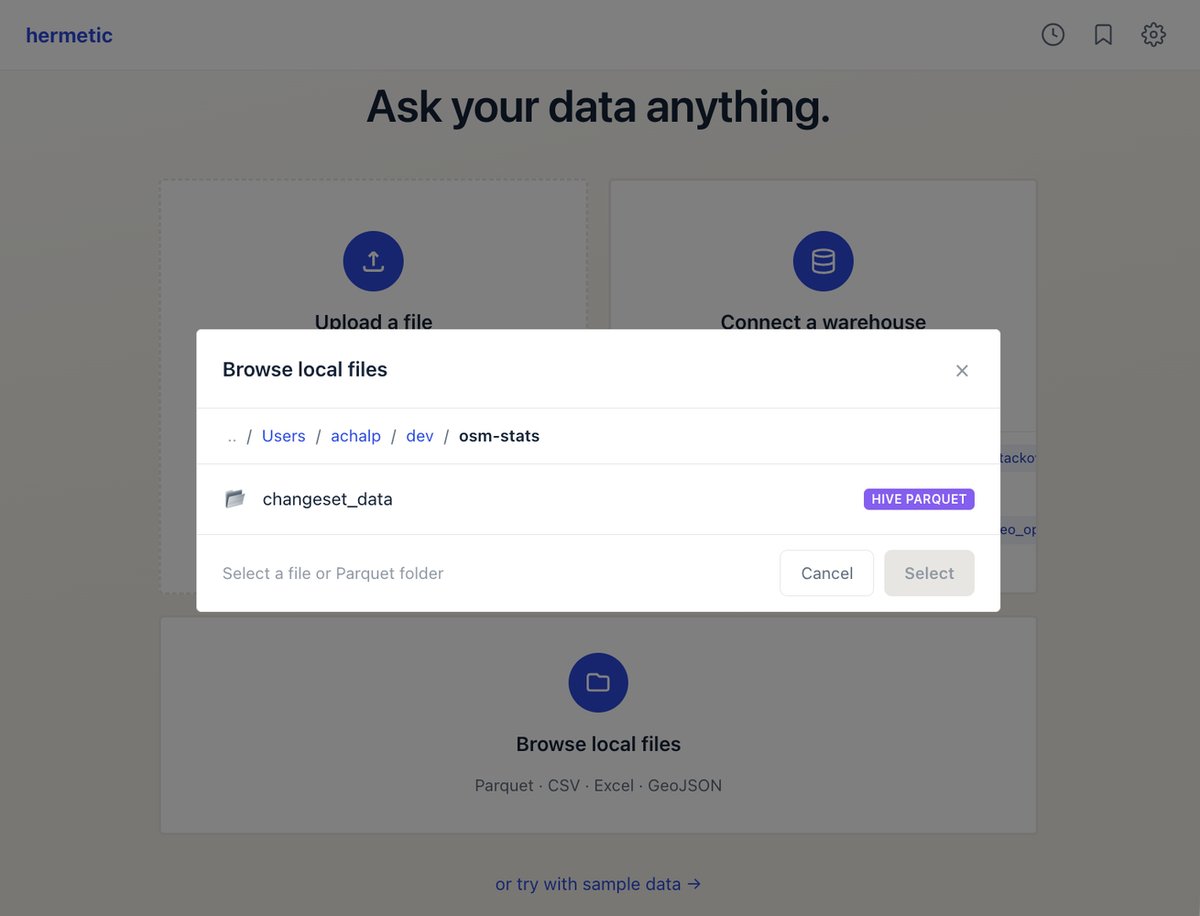
The last article announced warehouse connections. What’s new is local Parquet files and Hive-partitioned folders via DuckDB, with a file browser to pick them. No CSV conversion, no upload. Files get bind-mounted directly into the sandbox, zero-copy.
If you’re sitting on exports, data lake snapshots, or analytics outputs already in Parquet, you just point Hermetic at the folder and start asking questions. For anything over a million rows, the system pushes aggregation into DuckDB SQL before touching pandas. That’s the gap between working on sample data and working on the actual files on your laptop.
Charts that don’t break on real data
Chart count went from 8 to 31 across the last two releases. What changed since the last article isn’t new chart types. It’s making all of them actually work.
The rendering was fragile. When the LLM returned chart data as a nested object instead of a flat array (which happens a lot), every chart showed a blank rectangle. Line charts broke on long-format data. Legends overlapped when series names got longer than 12 characters. Axis labels piled up on dense datasets. Some chart labels were 9px, basically unreadable.
Targeted fixes for each:
- Charts auto-unwrap nested data objects, so
{data: [...], x_key, y_keys}works the same as a plain array - Line and area charts detect long-format data and pivot it client-side
- Legends size themselves from actual label lengths
- Labels truncate with tooltips instead of overlapping
- All chart text meets WCAG minimums (12px for UI, 11px for chart labels)
- Every chart supports full-height expanded rendering
None of this shows up in a feature list. But it’s why your charts actually render instead of showing a blank box the first time a column name is longer than “revenue.”
The plumbing underneath
Some of the worst bugs lived in the invisible pipeline between “warehouse returns results” and “chart appears on screen.”
BigQuery doesn’t support backslash escapes in LIKE patterns. The LLM kept generating MySQL-style \_ syntax, which just throws. ClickHouse overflows on Decimal arithmetic without explicit Float64 casts. Single-column query results (like SELECT DISTINCT year FROM ...) produce CSVs with no commas, and the parser was treating that as a fatal error instead of recognizing a one-column file. DuckDB’s read_csv can’t auto-detect delimiters when there’s only one or two rows.
Each warehouse dialect now gets targeted prompt guidance. The CSV parser treats “unable to detect delimiter” as a warning. A Python prelude injected before every sandbox script patches duckdb.sql to always specify delimiters, json.dump to handle NaN, and DataFrame.corr to auto-select numeric columns. Not elegant. But each one is a fix for a real query that broke in a specific, repeatable way.
What’s next
The conversation loop works but there’s room to make it smoother: better handling of empty warehouse results, smarter date range detection, richer context on follow-ups. After that, I want to see if local inference can get reliable enough that cloud API keys become optional rather than default.
If you’ve tried Hermetic and hit something that didn’t work, that’s genuinely the most useful feedback. Most of the fixes in this batch started with a real failure, not a plan.
GitHub: github.com/achalp/hermetic